Michal KuderskiDATA ANALYST · B.S. STATISTICS
Open to entry-level analyst opportunities

Michal Kuderski.

Data Analyst · Statistics graduate

Statistics grounded.
Decision focused.

I use Power BI, SQL, Python, R, and Excel to build reports, validate data, and explain what the results mean. My projects connect a statistics foundation with energy forecasting, healthcare spending analysis, and repeatable analytics workflows.

NIU · B.S. Statistics · 20263.7 GPA · Honors ProgramRomeoville, Illinois
Tools I use to answer questions
Power BI / DAXSQL / PostgreSQLPythonExcelRStatistics

01 / Selected work

Different data.
The same analytical discipline.

Explore case studies in energy forecasting, healthcare spending, validated analytics workflows, retail customer analysis, and research design. Each explains the question, methods, evidence status, and limits of the data.

01 · Forecasting & business intelligence
4.38% WAPE8,735 held-out hours · 13.2% lower MAE than the daily baseline
Independent portfolio project · Public release

GridCast | Energy Demand Forecasting & Power BI

An end-to-end PJM electricity-demand study connected to a four-page Power BI Service report, with 28 DAX measures, dimensional modeling, verified refresh, and model/date filters.

Power BIDAXPower QueryPythonForecasting

Official EIA-930 data. Public code and genuine report screenshots document the completed historical study and its forecasting limits.

Read the case study
02 · Spending & utilization
2,460 published records · 692 providers · 96 codes
Independent portfolio project

Medicare spending analysis

Where is payment concentrated, and how does utilization vary? I designed a normalized PostgreSQL schema and an Excel dashboard to examine cost drivers and provider variation.

SQLPostgreSQLExcelWeighted KPIs
Read the case study
03 · Analytics engineering
30,035 source records60 channel/month groups · independently reconciled
Independent project · Completed local demo

GraphOS | Validated Retail Analytics Demo

A Python analytics workflow that profiles fictional retail data, calculates cancellation-record shares, and presents clear results with inspectable evidence and saved-run history.

PythonData qualityValidationJavaScript

AI-assisted development. Demonstrated on a fictional benchmark; production-readiness work continues.

Read the case study
04 · Commercial analytics
246,739 chip line items71,287 customers · 21 segments · reconciled sales outputs
Quantium virtual job simulation

Retail customer & trial analysis

Who drives chip sales? My R-based simulation work examines customer segments and store trials. Key segment sales now reconcile to the raw data; original trial-effect claims remain unverified.

RCustomer segmentsStore matching

Virtual job simulation. Includes reconciled segment sales, aggregate-only downloads, and a separate diagnostic reconstruction of store comparisons.

Read the full case study
05 · Reporting automation
Read. Clean. Export.a repeatable Python-to-Excel workflow
Small sample-data demonstration

Python reporting automation

How can spreadsheet preparation become repeatable? My Python notebook reads an Excel sample, removes duplicate rows, standardizes column names, and exports cleaned data and descriptive summaries.

PythonpandasExcelJupyter
Question, method & scope

Output: Separate cleaned-data and summary-report workbooks generated from one notebook.

Scope: An automation demonstration, with no measured time-saving claim. A production payroll workflow would also need explicit type validation, error handling, and a documented missing-value policy.

Inspect the notebook ↗
View project repository
06 · Research design & simulation
Count-model simulation1,600 synthetic rows · empirical cultural findings unverified
NIU Honors capstone · Research design & simulation

Dreaming in Different Cultures

How would we compare language across dream narratives? The recovered capstone materials include a research plan and a synthetic count-model demonstration. They do not validate an observed cultural difference.

RSimulationPoisson GLMResearch design

Inspect the simulation source and evidence review. Mock topics and simulation-associated figures are clearly separated from empirical findings.

Read the full case study

Further statistical work

Further research and coursework in regression, model building, and experimental design.

Regression · R · Collaborative academic project

Student performance analysis

Our team examined survey variables and grade distributions for 145 students, comparing LASSO regression with stepwise variable selection in a co-authored technical report.

An observational sample; associations need broader validation before informing policy. Report co-authors: John Carrillo, Michal Kuderski, and Ethan Meadows.

Read the team’s technical report ↗

Classification · R · Coursework

Animal traits → class predictions

I explored classification trees and multinomial logistic regression using animal characteristics. The published R Markdown includes a tree visualization, class predictions, and a training-set confusion table.

The reported predictions use the training data; this demonstrates the modeling workflow, with held-out evaluation as the next validation step.

Inspect the modeling code ↗

Experimental design · Python & R

ANOVA under different assumptions

I simulated corn yield in a 3 × 3 Latin square, accounting for fertilizer, row, and column effects. Python and R analyses compare p-value distributions under normal and exponential errors.

A simulation study of test behavior and assumptions, with code and output published as PDFs.

Explore the simulation analysis ↗

02 / Healthcare case study

Follow the spending.
Question the denominator.

Medicare Provider Spending Analysis
CMS · Illinois psychiatry · 2023 data
PostgreSQL · SQL · Excel

Which services drive payment,
and what deserves a closer look?

I organized 2,460 published provider–procedure–place-of-service records into three related tables, wrote analytical SQL, and built a seven-sheet Excel workbook.

The aim was to explain spending concentration and provider variation with consistent metrics, then identify questions that the source alone cannot answer.

Finding
CPT 99214 accounts for $5.65M, or 20.8% of payment. The top five codes account for 55.6% of the cohort’s Medicare payment.
Interpretation
Submitted charges, allowed amounts, and Medicare payments answer different questions. Payment per service unit is a more defensible primary metric here than payment per summed beneficiary count.
Next decision
Examine high-volume codes and procedure mix first. Treat provider and city differences as leads for investigation before making staffing or access recommendations.
$27.2MMEDICARE PAYMENT
$35.6MALLOWED AMOUNT
$51.03PAYMENT PER SERVICE UNIT
532,675PUBLISHED SERVICE UNITS

Five codes account for 55.6% of payment.

Medicare payment · bars relative to the largest code

K1034 is a COVID-19 test code. Its 164,437 service units came from one provider. Procedure mix matters: a service unit is not necessarily a patient visit.

View exact values
Source: workbook → Procedure Analysis. Share uses total cohort Medicare payment.
CodeServicePaymentShare
99214Established outpatient visit$5,645,811.8820.8%
99213Established outpatient visit$3,070,132.3811.3%
99232Subsequent hospital care$2,690,318.199.9%
K1034COVID-19 test provision$1,933,779.127.1%
90833Psychotherapy with E&M$1,766,533.386.5%

Three measures. Three different meanings.

Reimbursement amounts · bars scaled to submitted charges

Medicare payment is 38.4% of submitted charges. The remaining charge amount is not automatically unpaid revenue or a loss; Medicare payment alone does not represent all provider receipts.

View exact values
Source: workbook → Specialty Summary. Totals reconstructed from published average amounts.
MeasureAmount
Submitted charges$70,702,611.15
Allowed amount$35,599,258.32
Medicare payment$27,182,697.04

Telephone-coded share varies sharply by provider city.

99441–99443 service units ÷ all published service units in that city · 0–100% scale

This describes billing-provider cities in a Medicare psychiatry cohort. It does not measure all psychiatric care, all telehealth, patient residence, or transportation barriers. Elk Grove Village and DeKalb each have one provider in this cohort, so their percentages need particular care.

Inspect denominators & provider counts
Source: Telehealth Access and Provider Outliers sheets. “Phone providers” counts providers billing the selected telephone codes.
Provider cityAll providersPhone providersPhone unitsAll unitsShare
Elk Grove Village1136848076.7%
DeKalb1126250152.3%
Plainfield5123993425.6%
Morris2114668221.4%
Pekin112191,16818.8%
Chicago188221,40973,5311.9%
What the denominator changes: CMS beneficiary counts are distinct within each published row. Summing them can count the same person more than once. I use payment per service unit in the headline KPIs and keep beneficiary-based outputs labeled as approximate. Higher payment per unit also does not establish lower efficiency or worse care.
Explore the method & limitations

Model the source grain

One row per provider NPI × HCPCS code × place of service. Providers and procedure codes are reference tables; utilization contains volumes and payment measures.

providers (NPI)utilization (fact)hcpcs_codes (code)

Weight the metrics correctly

Estimated payment = sum of average payment × service units. Payment per unit = total payment ÷ total units. This differs from an unweighted average of provider averages.

Screen variation, then investigate

CTEs and window functions compare providers within specialty. Distribution summaries are descriptive screens; procedure mix, volume, and case mix need further analysis before labeling a provider inefficient.

Separate patterns from causes

The file cannot establish access barriers, clinical outcomes, appointment availability, or why telephone use differs. Provider geography is not patient geography. Follow-up needs new data and a defined comparison.

Source: CMS Medicare Physician & Other Practitioners — by Provider and Service, 2023. Charts are static snapshots verified against the original workbook. The original workbook and PDF are retained; the SQL download includes a revised per-service comparison, the city-share query, and validation checks. It has not been rerun against the original source CSV as part of this website revision.

03 / Inspect the SQL

The reasoning is in the code.

Readable PostgreSQL, with the method beside it. Expand an example, wrap long lines, or copy the query to inspect it yourself.

Provider outlier screeningCTEs · weighted mean · RANK() window function
PostgreSQL · 77 lines
WITH provider_metrics AS (
    -- Individual provider-level payment per service
    SELECT
        p.npi,
        p.first_name,
        p.last_org_name,
        p.credentials,
        p.city,
        p.provider_type                                                 AS specialty,
        SUM(u.tot_srvcs)                                                AS total_services,
        SUM(u.tot_benes)                                                AS sum_benes_approx,
        ROUND(SUM(u.avg_medicare_payment * u.tot_srvcs), 2)             AS total_payment,

        -- Provider's own payment per service
        ROUND(
            SUM(u.avg_medicare_payment * u.tot_srvcs) /
            NULLIF(SUM(u.tot_srvcs), 0),
        2)                                                              AS provider_pay_per_svc,

        -- Specialty average payment per service (window function over specialty group)
        ROUND(
            SUM(SUM(u.avg_medicare_payment * u.tot_srvcs)) OVER (PARTITION BY p.provider_type) /
            NULLIF(SUM(SUM(u.tot_srvcs)) OVER (PARTITION BY p.provider_type), 0),
        2)                                                              AS specialty_avg_pay_per_svc

    FROM utilization u
    JOIN providers p ON u.npi = p.npi
    GROUP BY p.npi, p.first_name, p.last_org_name, p.credentials, p.city, p.provider_type
),

-- Add deviation from specialty mean and rank within specialty
ranked_providers AS (
    SELECT
        *,
        -- Absolute dollar deviation from specialty average
        ROUND(provider_pay_per_svc - specialty_avg_pay_per_svc, 2)     AS deviation_from_avg,

        -- Percent deviation from specialty average
        ROUND(
            (provider_pay_per_svc - specialty_avg_pay_per_svc) /
            NULLIF(specialty_avg_pay_per_svc, 0) * 100,
        1)                                                              AS pct_deviation,

        -- Rank within specialty (highest payment per service = rank 1)
        RANK() OVER (
            PARTITION BY specialty
            ORDER BY provider_pay_per_svc DESC
        )                                                               AS specialty_rank
    FROM provider_metrics
)

-- Final output: filter to providers who deviate > 50% from specialty mean
-- and have at least 10 services (low-volume providers can appear as outliers by chance)
SELECT
    specialty,
    specialty_rank,
    npi,
    CONCAT(first_name, ' ', last_org_name)  AS provider_name,
    credentials,
    city,
    total_services,
    sum_benes_approx,
    total_payment,
    provider_pay_per_svc,
    specialty_avg_pay_per_svc,
    deviation_from_avg,
    pct_deviation,
    CASE
        WHEN pct_deviation > 50  THEN 'HIGH OUTLIER'
        WHEN pct_deviation < -50 THEN 'LOW OUTLIER'
        ELSE 'Within Range'
    END                                     AS outlier_flag

FROM ranked_providers
WHERE ABS(pct_deviation) > 50
  AND total_services >= 10
ORDER BY specialty, pct_deviation DESC;

A ±50% threshold and a minimum of 10 service units are screening choices, not a formal significance test. A flagged provider needs further review of volume and procedure mix.

Telephone-coded share by cityConditional aggregation · explicit denominator · provider counts
PostgreSQL · 28 lines
WITH city_services AS (
    SELECT
        INITCAP(TRIM(p.city)) AS city,
        COUNT(DISTINCT p.npi) AS total_provider_count,
        COUNT(DISTINCT p.npi) FILTER (
            WHERE u.hcpcs_cd IN ('99441', '99442', '99443')
        ) AS telephone_provider_count,
        SUM(u.tot_srvcs) AS total_service_units,
        COALESCE(SUM(u.tot_srvcs) FILTER (
            WHERE u.hcpcs_cd IN ('99441', '99442', '99443')
        ), 0) AS telephone_service_units,
        COALESCE(SUM(u.avg_medicare_payment * u.tot_srvcs) FILTER (
            WHERE u.hcpcs_cd IN ('99441', '99442', '99443')
        ), 0) AS telephone_medicare_payment
    FROM utilization u
    JOIN providers p ON p.npi = u.npi
    WHERE p.state = 'IL' AND p.provider_type = 'Psychiatry'
    GROUP BY INITCAP(TRIM(p.city))
)
SELECT
    city, total_provider_count, telephone_provider_count,
    total_service_units, telephone_service_units,
    ROUND(telephone_medicare_payment, 2) AS telephone_medicare_payment,
    ROUND(100.0 * telephone_service_units
        / NULLIF(total_service_units, 0), 1) AS telephone_service_pct
FROM city_services
WHERE telephone_service_units > 0
ORDER BY telephone_service_units DESC, city;

Numerator: 99441–99443 service units. Denominator: all published service units in that provider city. Includes both total providers and telephone-code providers.

Check the source grainDuplicates · service volume · missing or negative payment
PostgreSQL · 13 lines
SELECT npi, hcpcs_cd, place_of_service, COUNT(*) AS row_count
FROM utilization
GROUP BY npi, hcpcs_cd, place_of_service
HAVING COUNT(*) > 1;

-- Null, non-positive volume, and negative-payment checks.
SELECT
    COUNT(*) AS published_rows,
    COUNT(*) FILTER (WHERE tot_srvcs IS NULL OR tot_srvcs <= 0)
        AS invalid_service_rows,
    COUNT(*) FILTER (WHERE avg_medicare_payment IS NULL
        OR avg_medicare_payment < 0) AS invalid_payment_rows
FROM utilization;

These checks look for data problems before interpreting results. They do not certify the full dataset or establish clinical validity.
04 / What I bring

Useful across industries.
Grounded in evidence.

The business context changes. Reliable data, sensible comparisons, and clear communication remain essential.

Structure & validate.

Use SQL and PostgreSQL to join records, design tables, calculate weighted metrics, and check duplicates or missing values. Use Python and pandas for repeatable transformations.

Evidence: Medicare schema and analysis · SQL examples

Analyze & challenge.

Apply a statistics foundation in regression, inference, ANOVA, and experimental design. Ask whether a result reflects the comparison, the denominator, or the underlying process.

Evidence: Retail evidence review · Count-model simulation

Explain & repeat.

Build Power BI reports with DAX measures, Power Query, dimensional models, and verified filters, alongside Excel dashboards and KPI summaries. Make the question, finding, and limitation clear enough for someone else to use.

Evidence: GridCast Power BI report · Medicare Excel dashboard

Skills you can trace to the work.

Methods and tools, paired with something you can inspect.

Technical skills, their application, and supporting project evidence.
CapabilityApplied methodsProject evidence
Power BI / DAX / Power QueryFour-page Service report, 28 DAX measures, dimensional modeling, refresh and model/date filter validationGridCast report captures and validation
SQL / PostgreSQLRelational schema design, joins, CTEs, window functions, weighted metricsInspect the SQL · Medicare case study
PythonForecasting, chronological model evaluation, data-quality checks, pandas transformations, workbook exportGridCast forecasting · GraphOS validation · Reporting automation
R & statistical analysisCustomer segmentation, store-comparison diagnostics, count-model simulation, variable selection, ANOVARetail trial · CURE capstone · Student analysis
Research design / simulationCount-data generation, Poisson offsets, diagnostic plotting; NLP proposed in the research designCapstone provenance review and simulation source
Predictive modelingHeld-out forecast evaluation, baseline comparison, interval coverage, classification trees, model interpretationGridCast model comparison · Classification coursework
Excel & reportingPivot tables, formulas, KPI summaries, charts, clear metric definitionsInspect the workbook ↓

Foundation & continued learning

Build. Check. Explain. Improve.

My Statistics degree provides a foundation in regression, inference, probability, and experimental design. My Applied Mathematics and Geography minors add quantitative and spatial perspectives.

GridCast demonstrates my Power BI Service report development, DAX, Power Query, and dimensional-modeling skills. I’m continuing to develop these skills through dashboarding and reporting automation; SAS experience comes through coursework. I use AI assistance to explore approaches, then check code, calculations, and interpretations against the evidence.

05 / Background

A statistics foundation.
A practical mindset.

Recent graduate. Careful with the numbers. Interested in what the analysis helps someone do next.

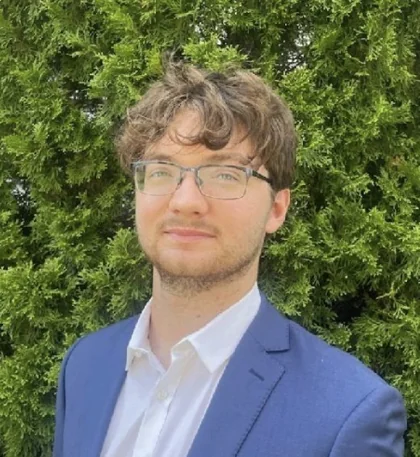
Michal Kuderski
Michal Kuderski
Romeoville · Chicago area

About me

I earned my B.S. in Statistics from Northern Illinois University in May 2026, with minors in Applied Mathematics and Geography and a 3.7 GPA.

I enjoy the point where technical work becomes useful: choosing the right measure, noticing an unexpected pattern, and explaining the result without overstating it.

Healthcare is one area where I’ve applied those skills. I’m open to analyst work across industries, including business operations, finance, insurance, education, and technology, wherever the role needs careful analysis and clear reporting.

My experience in inventory data entry and tennis instruction also informs how I work: check the details, communicate clearly, and keep improving the process.

Experience that transfers

Delivery DriverGenco Delivery LLC (Amazon deliveries) · Sep 2026 – Present
Manage delivery routes, scan packages, and maintain delivery records.
Certified Tennis InstructorNaperville Park District · Apr 2025 – Sep 2026
Coordinated recurring sessions for five participants, tracked progress, and provided feedback.
Data Entry & Inventory ControlGEODIS · Dec 2024 – Feb 2025
Verified about 100 shipment records daily and corrected Excel datasets exceeding 1,000 rows.
Tennis CoachNIU Tennis Club · Aug 2023 – May 2024
Coaching and communication experience alongside my statistics coursework.

Education & analytical tools

B.S. Statistics · Northern Illinois University · University Honors Program

Coursework: Regression Analysis, Statistical Inference, and Design & Analysis of Experiments (SAS).

Project tools: Power BI Service, DAX, Power Query, SQL / PostgreSQL, Python, R, Excel, Git, Jupyter. Coursework: SAS.

Languages: English · Polish

Certificates

  • Meta Data Analyst with GenAI Professional Certificate · Coursera · 2025
  • Intermediate SQL · DataCamp · 2025
  • Data Analysis in Excel · DataCamp · 2026

Honors capstone · Completed May 2026

Dreaming in Different Cultures

My capstone proposed a cross-cultural DreamBank study. Recovered source files document a synthetic count-model demonstration and an incomplete empirical workflow. The case study identifies what the code establishes and what remains unverified. Explore the capstone ↗

06 / Resume

The experience, on one page.

The general version leads with forecasting and reporting. The healthcare version leads with Medicare payment and utilization analysis.

07 / Let’s connect

Have a question
worth answering?

I’m seeking entry-level Data Analyst and related opportunities. If your team needs someone who can work carefully with data and explain what it means, I’d welcome a conversation.

Based in Romeoville, Illinois
Interested in local on-site, hybrid, and remote opportunities